Kafka replaces your middlewares — a 200-store supply chain run by 3 AI agents
TL;DR — What a distributor takes 4 hours to process — detect a stockout, decide on replenishment, execute the transfer, trace the decision — three AI agents on Kafka do it in 30 seconds. MCP Confluent to query topics in natural language, KIP-932 for elastic scaling, a business skill for decision logic. Zero middleware, executable code.
In this article
- 1. Why this article, why now
- 2. The use case — retail replenishment
- 3. Why Kafka over an orchestrator
- 4. MCP Confluent — the agent that sees Kafka as an API
- 5. Business skill — decision logic without code
- 6. KIP-932 Share Groups — native elastic scaling
- 7. The complete pipeline in 30 seconds
- 8. What actually runs
- 9. Demo and next step
- References
1. Why this article, why now
| The evolution of Kafka and AI agents converged over a decade. Two distinct trajectories — one on the streaming infrastructure side, the other on the agent frameworks side — that join up in 2026 to the point of no longer requiring the slightest glue layer. |
Two recent building blocks change the game:
| Building block | Date | What it is | Reference |
|---|---|---|---|
| MCP Confluent | GA July 2026 | An open-source MCP server that exposes 50+ Kafka primitives — topics, consumer groups, Avro schemas, Flink SQL, connectors — as callable tools in natural language by any compatible agent (Claude, Cursor, ADK). The agent doesn’t learn the Kafka protocol; it calls tools, the MCP translates. | Confluent Docs · GitHub |
| KIP-932 Share Groups | GA April 2026 (broker/Java) | Introduces share groups: cooperative consumption where N consumers read the same partitions without the 1 consumer = 1 partition constraint. Each message follows a fetch → lock → ack/release cycle, with native retry (delivery_count). Kafka becomes a task queue, without RabbitMQ. Note: the confluent-kafka Python client is still in Preview — only the Java API is GA. |
KIP-932 (Apache) |
What this article demonstrates: these two building blocks in action on a concrete use case.
- Domain: replenishment of a distribution chain — 200 stores, 50 products
- Result: 4 hours of manual workflow → 30 seconds of automated pipeline
- Why this use case: it’s the field I currently work in — the data platform of a major French retail player. Replenishment is a representative textbook case of the challenges encountered there: thousands of real-time flows (stock levels dropping), decisions that must be traceable (regulatory audit), and unpredictable load spikes (200 anomalies at 8am, 3 at 2pm). These are the same constraints found in fraud detection, content moderation, or maintenance — any pipeline where specialized agents must cooperate on events without glue middleware. If the pattern holds here, it transfers.
2. The use case — retail replenishment
A distributor operates 200 stores, each carrying 50 products. Each product has a minimum stock threshold per store. As soon as stock drops below that threshold, an anomaly is detected, a replenishment decision is made — transfer from a neighboring store or supplier order — the task is executed, and the operation is logged.
flowchart TD
    A["Network of 200 stores × 50 products<br/>each product has a minimum threshold per store"] --> B{"Product stock<br/>< minimum threshold?"}
    B -- No --> A
    B -- Yes --> C["Anomaly detected<br/>(imminent stockout)"]
    C --> D{"Does a neighboring store<br/>have stock available?"}
    D -- Yes --> E["Decision: internal transfer<br/>from neighboring store"]
    D -- No --> F["Decision: supplier order"]
    E --> G["Task execution<br/>(transfer or order)"]
    F --> G
    G --> H["Traceability: audit log"]
The current manual workflow — information gathering, analysis, validation, execution — takes about 4 hours per anomaly. With 200 stores and 50 products, the daily volume of anomalies can reach several hundred. Automation isn’t a luxury; it’s an operational necessity.
The use case is deliberately simplified — 200 stores, 50 products, a single decision rule. The goal isn’t to model a real distribution network with its warehouses, logistical constraints, and multiple suppliers, but to isolate the architectural pattern: how agents cooperate on Kafka without glue middleware. Business complexity is added by enriching the
SKILL.md— the architecture doesn’t change.
The complete source code, detailed business rules, and instructions for running the PoC are on github.com/arabaaoui/kafka-for-agents.
3. Why Kafka over an orchestrator
We could have built this with a workflow engine, a task queue, a Python orchestrator. The problem is that each component would have required a different middleware:
| Component | Classic approach | Problem |
|---|---|---|
| Querying data streams | Custom REST API on Kafka | A glue layer to maintain |
| Distributing tasks | RabbitMQ or SQS | Two stacks to operate |
| Preventing duplicate executions | Distributed lock (Redis) | Yet another component to monitor |
| Tracing decisions | Audit database | Kafka → DB sync to build |
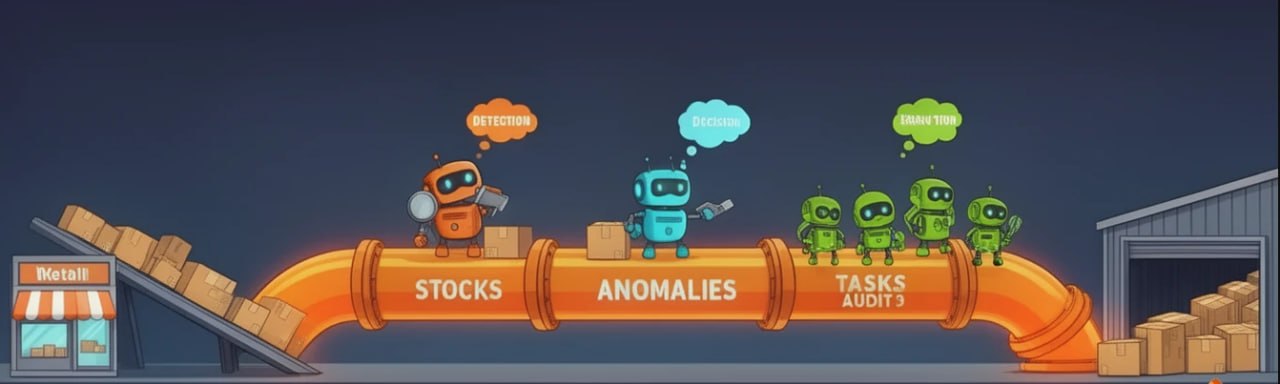
The chosen architecture takes the opposite bet: everything on Kafka. No glue. No middlewares. Three agents, five topics, and the platform’s native primitives.
graph TB
    SIM["Simulator<br/>200 stores × 50 products"] -->|stocks| KAFKA

    subgraph KAFKA["Apache Kafka 4.2.1 (KRaft)"]
        STOCKS[("stocks")]
        ANOMALIES[("anomalies")]
        TASKS[("tasks")]
        AUDIT[("audit")]
    end

    STOCKS -->|poll 5s| DET["Detection Agent<br/>MCP Confluent"]
    DET -->|produce_anomaly| ANOMALIES
    ANOMALIES -->|poll 3s| DEC["Decision Agent<br/>Business SKILL.md"]
    DEC -->|produce_task| TASKS
    DEC -->|log_audit| AUDIT
    TASKS -->|ShareGroup KIP-932| EXE["Execution Agent ×N<br/>horizontal scaling"]
4. MCP Confluent — the agent that sees Kafka as an API
The Detection Agent has no hardcoded KafkaConsumer. It uses the MCP Confluent
server — a bridge that exposes Kafka primitives (consume-messages, list-topics,
get-topic-config) as tools that the ADK agent can call in natural language.
sequenceDiagram
    participant K as Kafka (stocks)
    participant P as Detection Agent (ADK)
    participant M as MCP Confluent
    participant A as Kafka (anomalies)

    K->>P: stock P-42 = 5, min_threshold = 20
    P->>P: deterministic pre-filter: 5 < 20 → candidate
    P->>M: call_mcp("consume-messages", {topic:"stocks", max_messages:5})
    M-->>P: recent history of product P-42
    P->>P: LLM qualification: severity, trend
    P->>A: produce_anomaly("stockout", CRITICAL)
The agent doesn’t “know” how to query Kafka. It knows how to call tools. The MCP bridge translates. If tomorrow we switch Kafka clusters, the agent doesn’t change — only the MCP endpoint changes.
5. Business Skill — decision logic without code
The Decision Agent doesn’t contain if neighbor_stock > needed: transfer() else: supplier_order().
Its logic lives in a SKILL.md file, read once at startup and injected into
the agent’s instruction:
SKILL: supply-chain-replenishment
1. Identify the product and store concerned
2. Check stock of neighboring stores (same region)
3. If transfer possible → generate transfer order
4. Otherwise → generate priority supplier order
5. If perishable product → adjust quantity (buffer +10%)
6. Log the decision in the audit topic
sequenceDiagram
participant A as Kafka (anomalies)
participant P as Decision Agent (ADK)
participant S as Kafka (neighbor stocks)
participant T as Kafka (tasks)
participant AU as Kafka (audit)
Note over P: instruction = prompt + SKILL.md<br/>(loaded at startup)
A->>P: anomaly: P-42, Lyon-Part-Dieu, qty=5
P->>S: get_neighbor_stocks("Lyon", "P-42")
S-->>P: Bellecour: 200u, Confluence: 80u
P->>P: applies SKILL.md → transfer possible
P->>T: produce_task(transfer, 50u, Bellecour→Part-Dieu)
P->>AU: log_audit(decision, reason=neighbor with surplus)The business team can modify the rule without touching a single line of Python. The skill is in Git — versioned, reviewable, auditable. A
docker compose restart decision-agentand the new rule is in production.
6. KIP-932 Share Groups — native elastic scaling
At 8 AM, 200 anomalies are detected (overnight peak). The Execution Agent must process 200 tasks within minutes.
Without share groups, scaling is capped by the partition count: 3 partitions = 3 agents max. With KIP-932, all agents cooperate on the same partitions:
stateDiagram-v2
    [*] --> AVAILABLE: task produced in tasks
    AVAILABLE --> ACQUIRED: fetch by Agent-7 (lock 30s)
    ACQUIRED --> ACKNOWLEDGED: ACK after successful execution
    ACQUIRED --> AVAILABLE: agent crash → lock expires → retry
    ACQUIRED --> DEAD: delivery_count > 5 → dead letter

    note right of ACQUIRED
        The N-1 other agents continue
        to fetch on the same partitions.
        No rebalance. No limit.
    end note
# Load spike at 8 AM
docker compose up -d --scale execution-agent=20
# → 200 tasks processed in 2 minutes
# Lull at 2 PM
docker compose up -d --scale execution-agent=2
# → scale down without rebalance, without message lossKafka becomes a native task queue. No need for RabbitMQ alongside it. The native
delivery_counthandles retries. If an agent crashes mid-processing, the lock expires after 30 seconds and the task is automatically put back into circulation.
7. The complete pipeline in 30 seconds
sequenceDiagram
    participant S as Simulator
    participant D as Detection (ADK + MCP)
    participant DEC as Decision (ADK + SKILL.md)
    participant E as Execution ×N (KIP-932)
    participant A as Audit

    S->>D: stock P-42 Lyon-Part-Dieu = 5 (threshold=20)
    D->>D: pre-filter → MCP → CRITICAL qualification
    D->>DEC: anomaly: stockout, P-42, Part-Dieu

    DEC->>DEC: checks neighbors → Bellecour has 200u
    DEC->>DEC: SKILL.md → internal transfer 50u
    DEC->>E: task: transfer(Bellecour→Part-Dieu, 50u)
    DEC->>A: audit: decision=transfer, reason=neighbor surplus

    E->>E: executes transfer (ACK after success)
E->>A: audit: task completed, 2.0s| Step | Duration | What happens |
|---|---|---|
| t=0s | — | The simulator publishes a stock below threshold |
| t=5s | +5s | The Detection Agent qualifies the anomaly via MCP |
| t=8s | +3s | The Decision Agent selects the transfer by applying SKILL.md |
| t=10s | +2s | The Execution Agent processes the task and acknowledges |
| t=10s | — | The decision is logged in the audit trail |
30 seconds for what took 4 hours in a human circuit. Without a single hardcoded if in
the business logic. No glue middleware between the components.
8. What actually runs
The PoC is executable — not a mockup, not print() statements pretending to work.
Each agent is a real google.adk.Agent with a real LLM behind it:
| Agent | Stack | Deterministic mode |
|---|---|---|
| Detection | ADK + LiteLLM (OpenAI/Anthropic/Gemini) + MCP Confluent | Basic anomaly without LLM qualification |
| Decision | ADK + SKILL.md injected + real Kafka tools | Default supplier order |
| Execution | Native ShareConsumer (ACK/RELEASE/REJECT) + native scaling | Fixed 2s delay, 100% success |
And if you don’t have an LLM key handy, each agent falls back to deterministic mode. The pipeline runs end-to-end without paying anything.
Note on the native ShareConsumer — the
confluent-kafkaPython client exposesShareConsumerin Preview since version 2.15.0. The PoC uses it directly for the KIP-932 lifecycle —AVAILABLE → ACQUIRED → ACKNOWLEDGED, lock expiration, retry counter, dead-letter. One limitation of the Preview client: noRENEWaction, which prevents extending a lock during a long LLM call — a slow agent risks losing its lock before acknowledging. Full details in the repo README.
git clone https://github.com/arabaaoui/kafka-for-agents.git
cd kafka-for-agents
cp .env.example .env   # leave empty = fully deterministic
make all               # Kafka test cluster + agents + simulator
make check             # verify everything is running
Kafka UI on http://localhost:8081 lets you see messages flowing in real time across the 5 topics. make check displays consumer group states, message counts per topic, and the latest anomalies/tasks.
9. Demonstration and Next Step
What this article demonstrated:
- MCP Confluent allows an AI agent to query Kafka without knowing the Kafka protocol — it calls tools, the MCP translates. The Detection Agent consumes inventory, qualifies anomalies, and publishes to the
anomaliestopic. - A business skill in a simple
SKILL.mdfile is enough to guide an agent’s decisions without hardcoding the logic. The Decision Agent checks neighboring stock, chooses between transfer and supplier order, and traces every decision. - KIP-932 Share Groups turns Kafka into a native task queue with elastic scaling. The Execution Agent scales from 2 to 20 instances in one command, with no rebalance, no partition limit, no RabbitMQ. The PoC uses the Python
ShareConsumerclient directly (Preview since version 2.15.0), with the exception of theRENEWaction, absent from this client until it reaches GA. - The full pipeline — 200 stores, 50 products, three agents — runs in 30 seconds end to end, where the human circuit took 4 hours.
This architecture eliminates two middlewares: the data access glue (MCP replaces AKHQ/REST API scripts) and the external task queue (KIP-932 replaces RabbitMQ/SQS). But it relies on a business skill loaded locally — a markdown file mounted in a container.
The next article changes scope: the agents are no longer in the business flow — they’re around it: ops. A poison message blocks a billing consumer group. The agent diagnoses the exact cause via MCP in 2 minutes — where an ops engineer would take 30 to 90 minutes by hand. The fix remains manual: a 30-second CLI command. No cluster writes, no delegated autonomy — the agent eliminates diagnostic time, not human judgment. A concrete use case, as always.
References
- MCP Confluent — open-source MCP server exposing Kafka to AI agents: Confluent documentation · source code
- KIP-932: Queues for Kafka — share groups and cooperative consumption: KIP on the Apache Kafka wiki
- PoC kafka-for-agents — full source code of the supply chain pipeline: github.com/arabaaoui/kafka-for-agents
Commentaires